Timing report - certificate cleanup and service account credentials
Summary
A maintenance job with a new cleanup step removed old and stale certificates. A subsequent deployment to a staging environment forced a certificate reload, which caused the production server to become unavailable.
Restoring the certificates was not sufficient on its own. The service recovered fully once the service account credentials were re-entered and Windows picked up the restored certificates.
Measurable customer impact ran from 13:16 to 15:00 CEST (11:16 to 13:00 UTC) – roughly 1 hour 45 minutes, including two separate periods of disruption.
The incident has also highlighted unnecessary complexity in parts of our current server setup. This complexity was the direct cause of the outage, but simplifying the setup will make the environment easier to maintain and reduce the risk of similar issues in the future.
Follow-up actions
Following the incident, we are taking a number of corrective and preventive actions:
Additional testing: Maintenance jobs and changes will be tested more thoroughly before being introduced into production.
Simplifying the server setup: We are working together with our hosting partner, Unit-IT, to simplify the current infrastructure and remove unnecessary complexity.
Data migration: As part of this work, approximately 2.5 TB of data needs to be moved. This will take some time, but the migration can be carried out in the background without affecting users.
Reducing complexity: Once the data migration is complete, we will be able to remove parts of the existing setup and simplify the overall server environment.
Further preventive measures: We are reviewing additional measures to reduce the risk and impact of similar incidents in the future.
This work has already started and will continue over the coming days and into next week.
Current status
The production environment is running normally, and we do not currently expect the ongoing work to cause further disruption.
Some staging environments are not yet working 100%, and we are continuing to work on these.
If any other issues are currently being experienced, please report them to SpeedAdmin Support so they can be investigated.
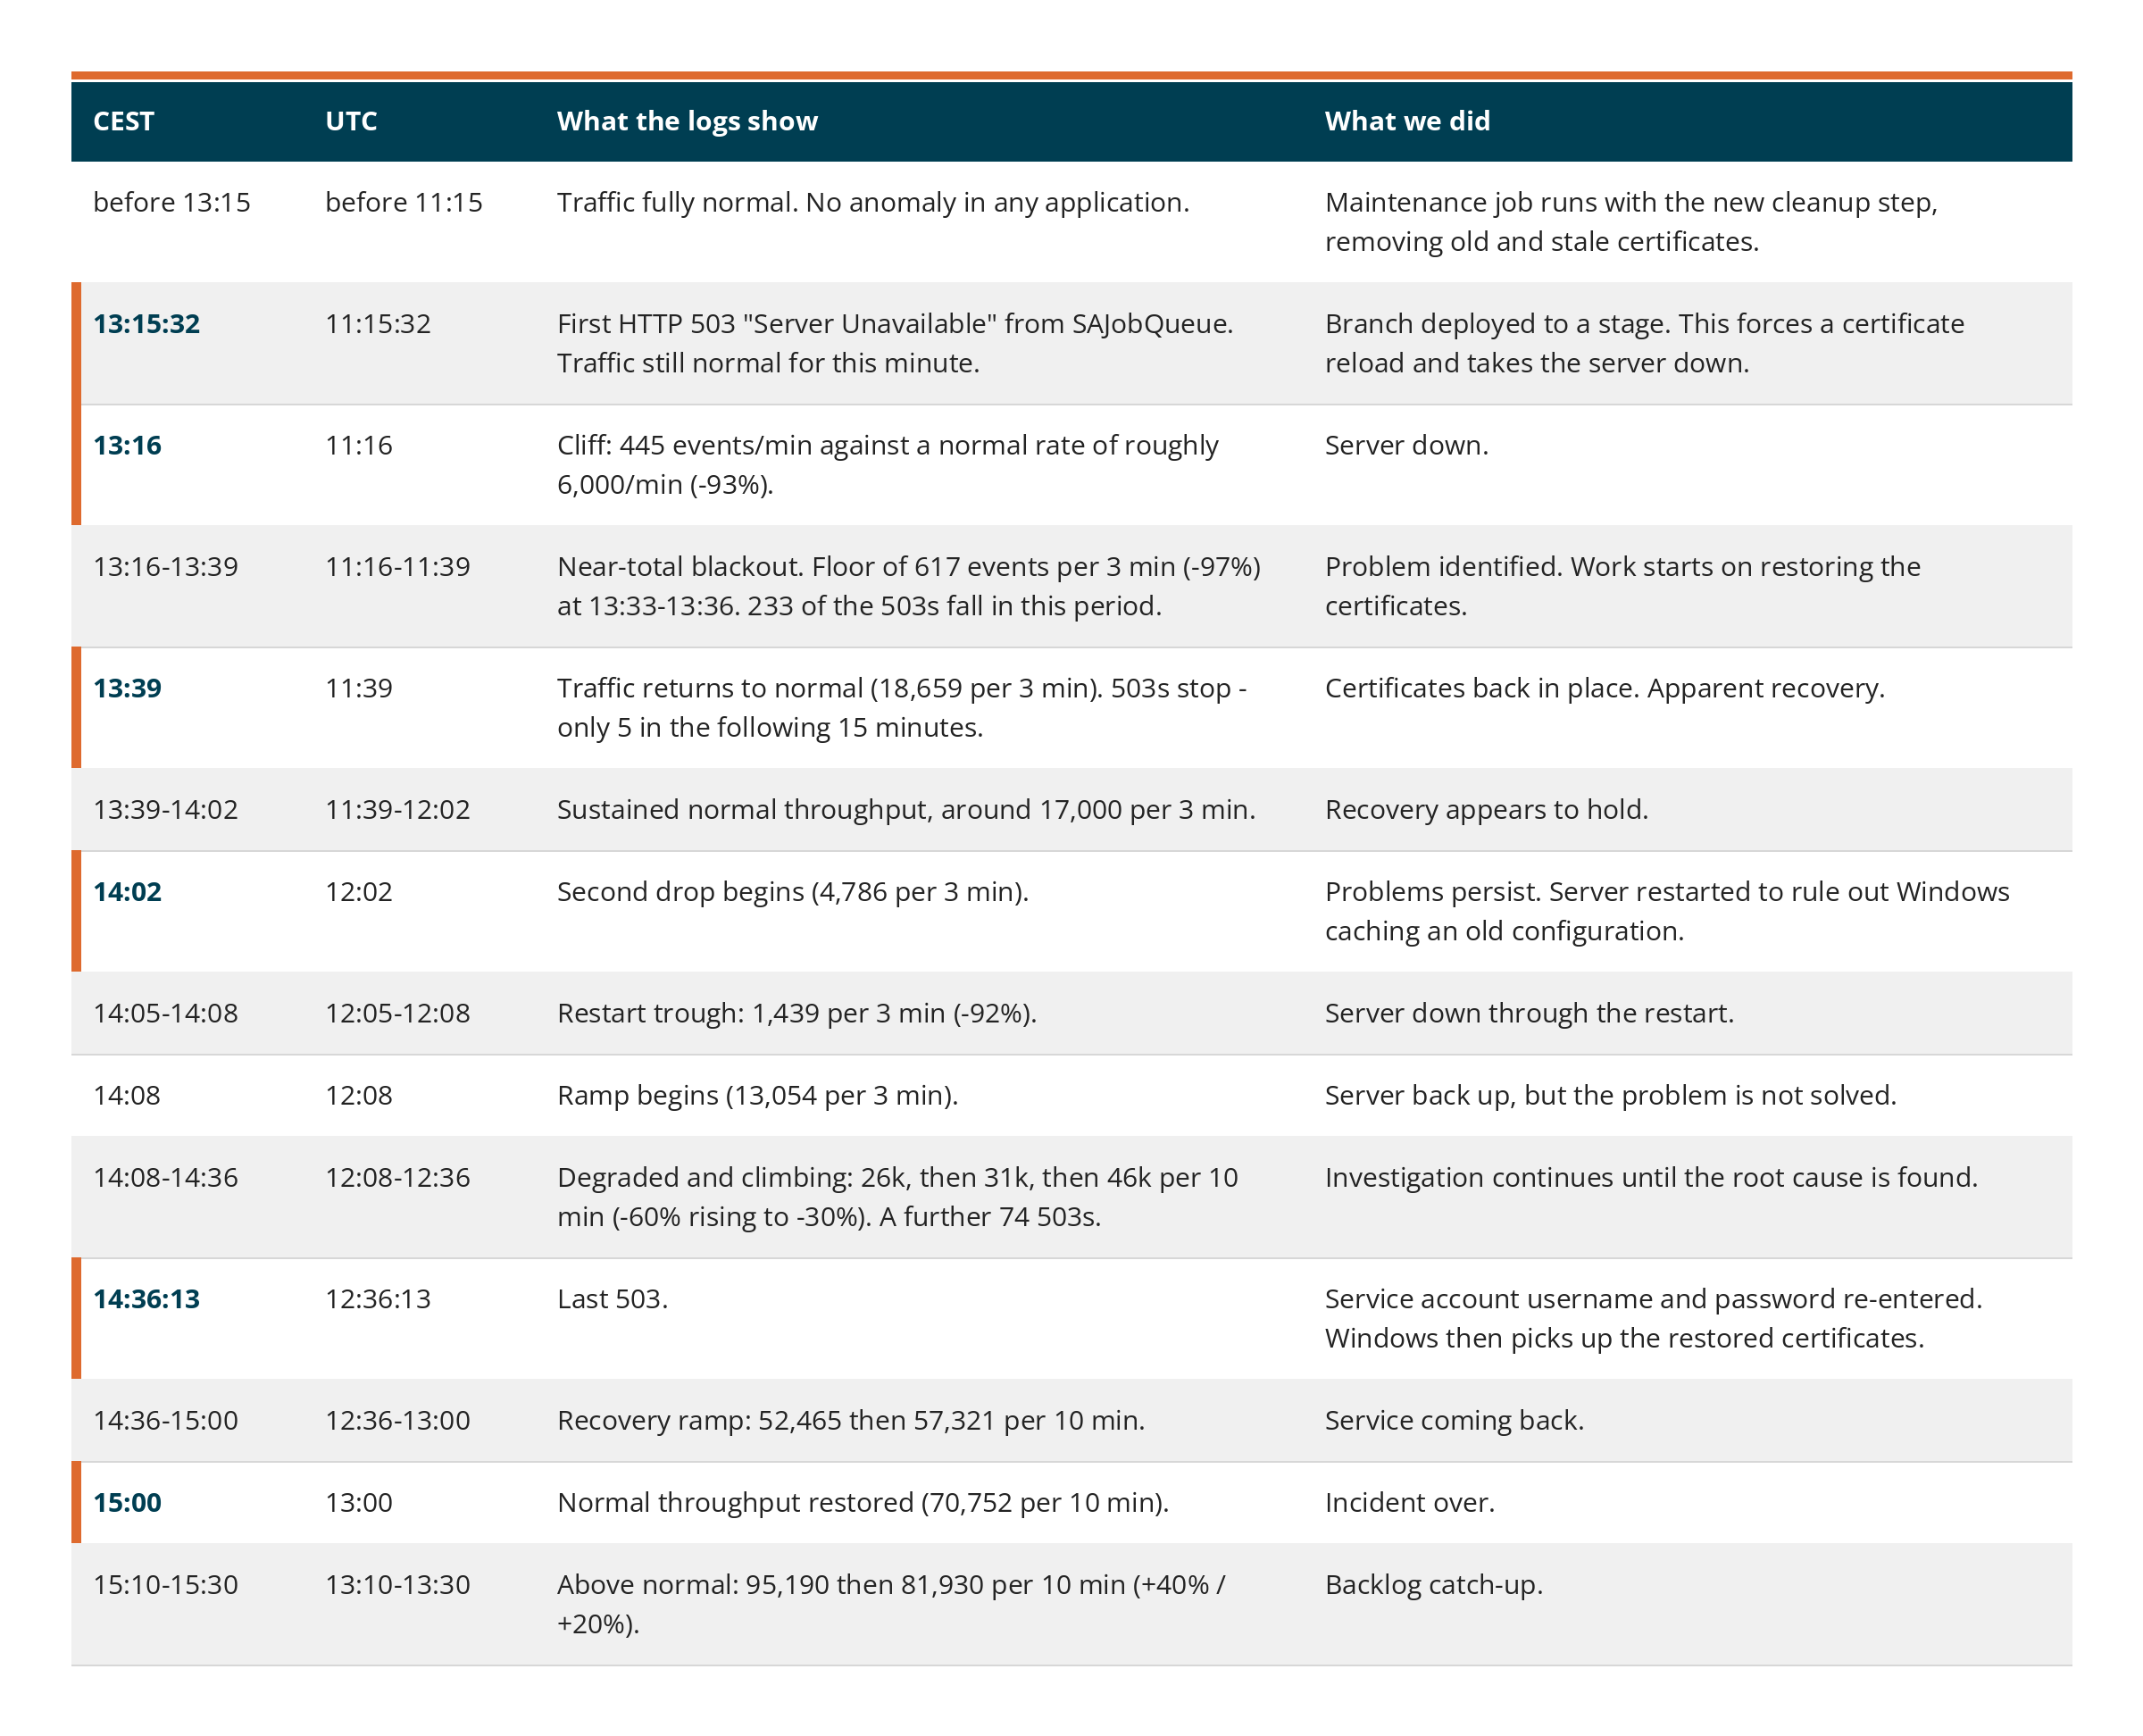
Merged timeline
Points worth stating
It was two outages, not one. Near-total unavailability 13:16-13:39 (about 23 minutes), full recovery for roughly 23 minutes, then a second degraded period 14:02-15:00 that began with the restart
The system never went fully dark. The floor was about 3% of normal traffic, not zero, so some requests were served throughout.
Restoring the certificates was not the fix. Traffic recovered fully at 13:39 and then failed again at 14:02, which is why the restart followed. The incident only closed once the service account credentials were re-entered at 14:36.
One attribution caveat. The 14:02-14:08 trough matches the restart closely, but the logs show the traffic drop, not the restart itself. The link is inferred from the team account and could be confirmed against the Windows event log if needed.
Going forward. More testing of maintenance job before alteration.